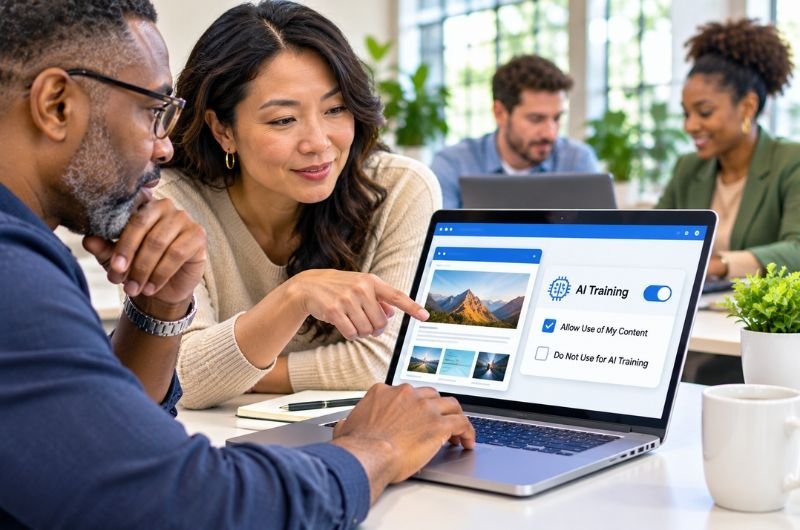
Google, OpenAI, Microsoft and Anthropic are supporting a new approach that could give website owners greater control over whether their online content is used to train artificial intelligence systems. Announced October 30, the proposal would allow publishers, businesses and individual creators to communicate their preferences to multiple AI companies through a single website setting.
For years, websites have relied on a file called robots.txt to provide instructions to automated programs that visit their pages. But controlling AI training has become increasingly complicated, with different companies using different systems. The proposed approach would simplify that process, allowing website operators to indicate whether their content may be used for AI training without having to manage separate instructions for every participating company.
The change could be particularly significant for news publishers, independent writers, photographers and other creators whose original work appears online. As AI systems become more capable of generating articles, images and other material, concerns have grown over how that technology is trained and whether creators have a meaningful say in the use of their work. A common preference system could make those decisions easier to communicate, although it would not automatically prevent every company from using publicly available material.
The new controls are not fully operational yet. OpenAI expects to implement the shared signal in the coming months, while Google is targeting 2027 and Microsoft plans to begin honoring the new preferences in February 2027. Anthropic has begun implementation work. The proposal also remains a draft rather than a formally adopted internet standard, and companies may apply the preferences differently depending on whether content is being used for AI training or to help generate answers.
The Readovia Lens
The proposed AI training controls highlight a growing challenge in the AI era: how can websites remain visible and accessible while protecting the value of their original work? Publishers and creators depend on online discovery to reach audiences and generate revenue, but that doesn’t necessarily mean they want their content used to train AI models. Giving website owners a clearer voice in that decision is a meaningful step forward. The bigger test will be whether AI companies consistently respect those choices.